Sovereign AI & Local Model Runtimes
Tekcent configures, services, and maintains localized open-weights AI runtimes giving enterprises complete data control, local hardware efficiency, and zero external API dependencies.
Why Organizations Need Local AI Infrastructure
Relying on public cloud AI APIs introduces data privacy risks, unexpected token billing, and compliance headaches. Sending sensitive enterprise information over third-party networks often breaches local data residency policies. Tekcent sets up and services leading open-weights foundation models including DeepSeek, Qwen, and Llama directly within your private network or on-premise infrastructure, guaranteeing every prompt, query, and output remains strictly under your control.
Built for:
Financial, healthcare, and corporate environments with strict compliance rules
Organizations requiring 100% offline or air-gapped operational capability
Software teams needing secure, localized developer sandboxes and API endpoints
What Makes Tekcent’s Sovereign Runtimes Different
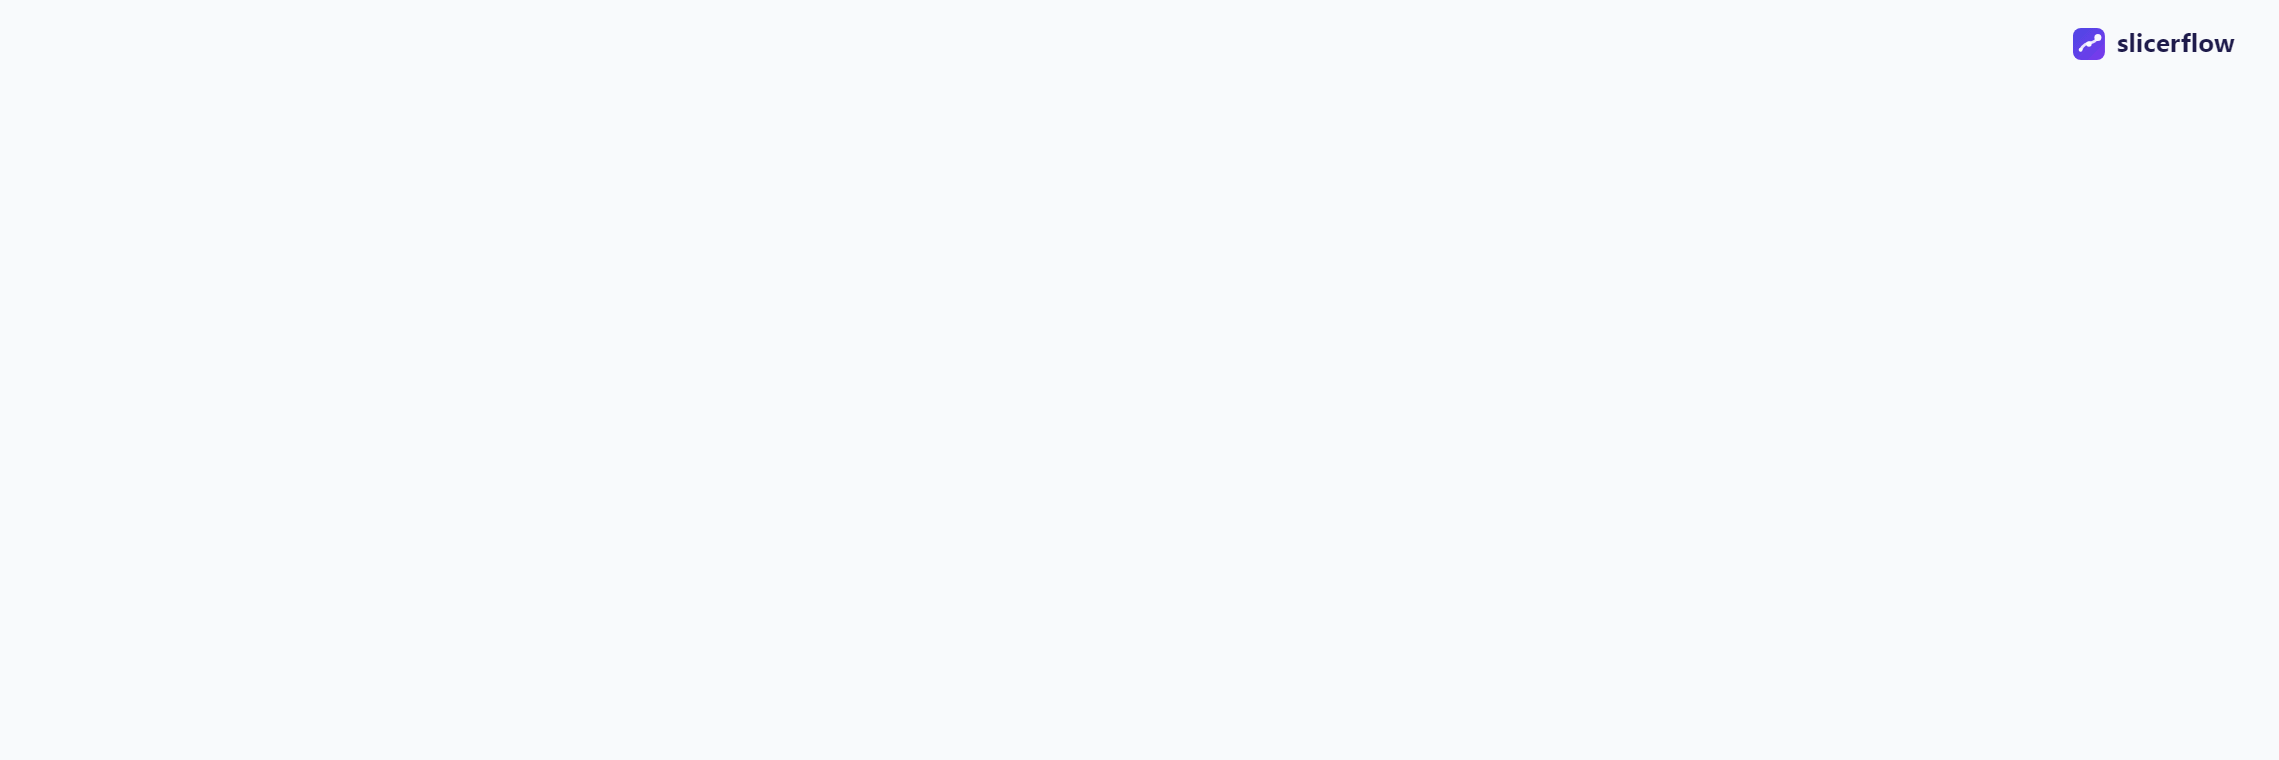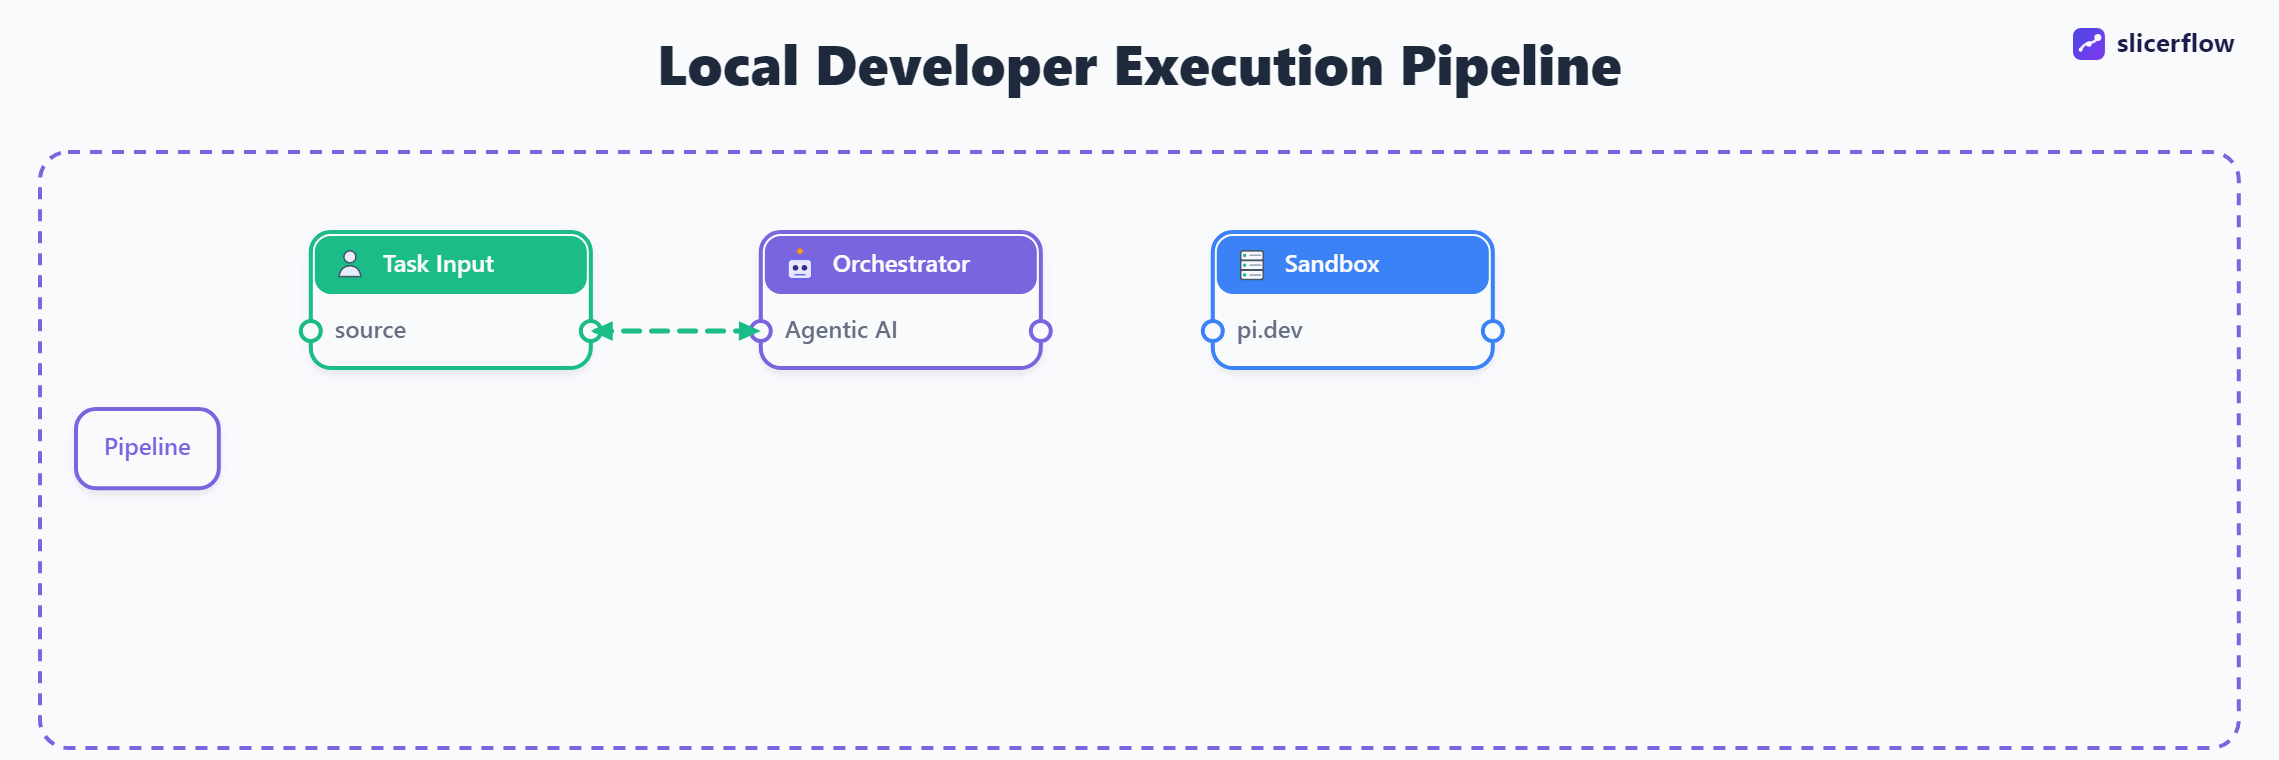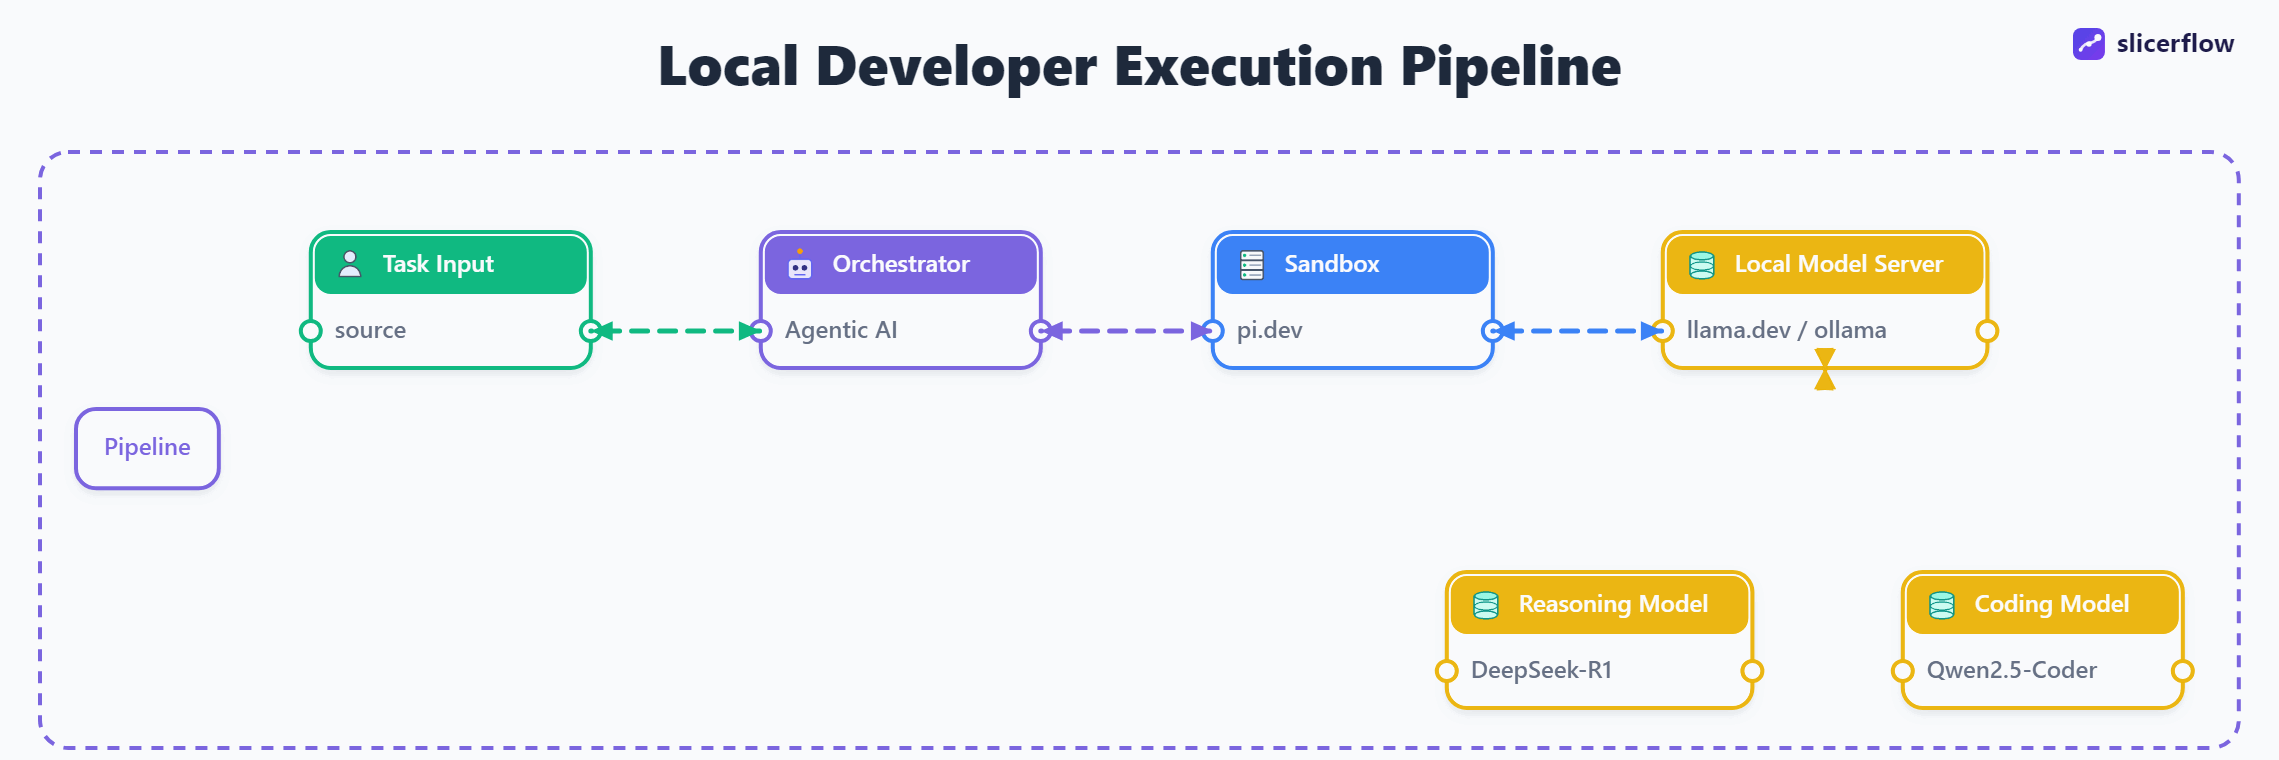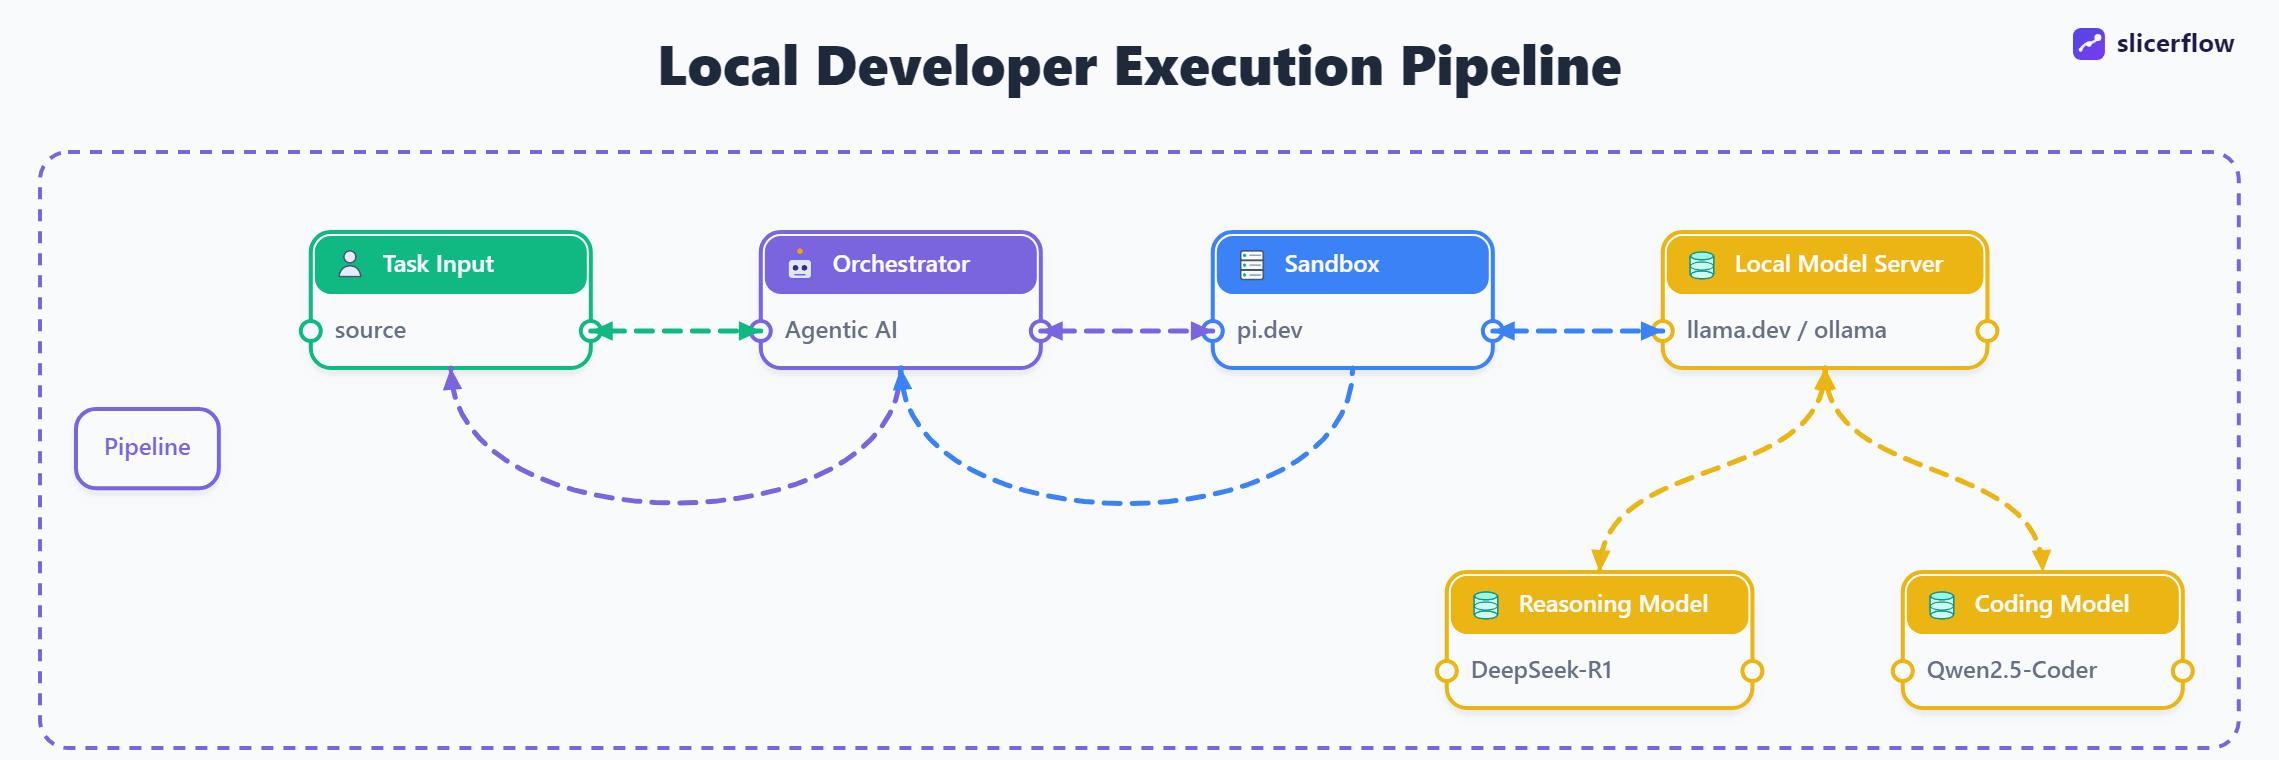
Turnkey Local Setup (Ollama, llama.dev & pi.dev): We configure and service Ollama, llama.dev, and pi.dev environments to deliver fast, lightweight, and localized model runtimes across developer workstations and internal servers.
Leading Open-Source Model Servicing (DeepSeek, Qwen, Llama): We deploy, fine-tune, and maintain state-of-the-art open-weights models such as DeepSeek-R1/V3, Qwen 2.5, and Llama 3 tailored to your specific enterprise workloads and data structures.
Hardware Optimization & Quantization: We apply INT4/INT8 quantization techniques to run 8B, 14B, 32B, and 70B+ parameter models efficiently on existing local servers without requiring massive hardware overhauls.
Air-Gapped & Offline Security: Execute AI workloads in completely isolated environments with no outbound internet access eliminating third-party data leakage risks.
Secure Local API Integration: We wrap local runtimes in custom REST endpoints, enabling your internal apps, tools, and workflows to query local models safely with role-based access control.
Technical Architecture & Local Pipeline
Environment Configuration: Setting up Ollama, llama.dev, pi.dev, and local model container environments on target enterprise infrastructure.
Model Optimization: Applying model quantization (INT4/INT8) to balance inference speed with local hardware memory constraints across DeepSeek, Qwen, and Llama weights.
API Gateway Binding: Connecting local runtimes to internal Active Directory / OAuth authentication systems for permissioned employee access.
Maintenance & Servicing: Ongoing model updates, context optimization, and local runtime servicing as open-source foundation models evolve.
Private AI Services for Enterprise
Ready for change?
If the time is now for you to transform the way you do business, we’re here to help — every step of the way.